The NocoDB Attachment That Wouldn't Update (and a Regex That Missed)
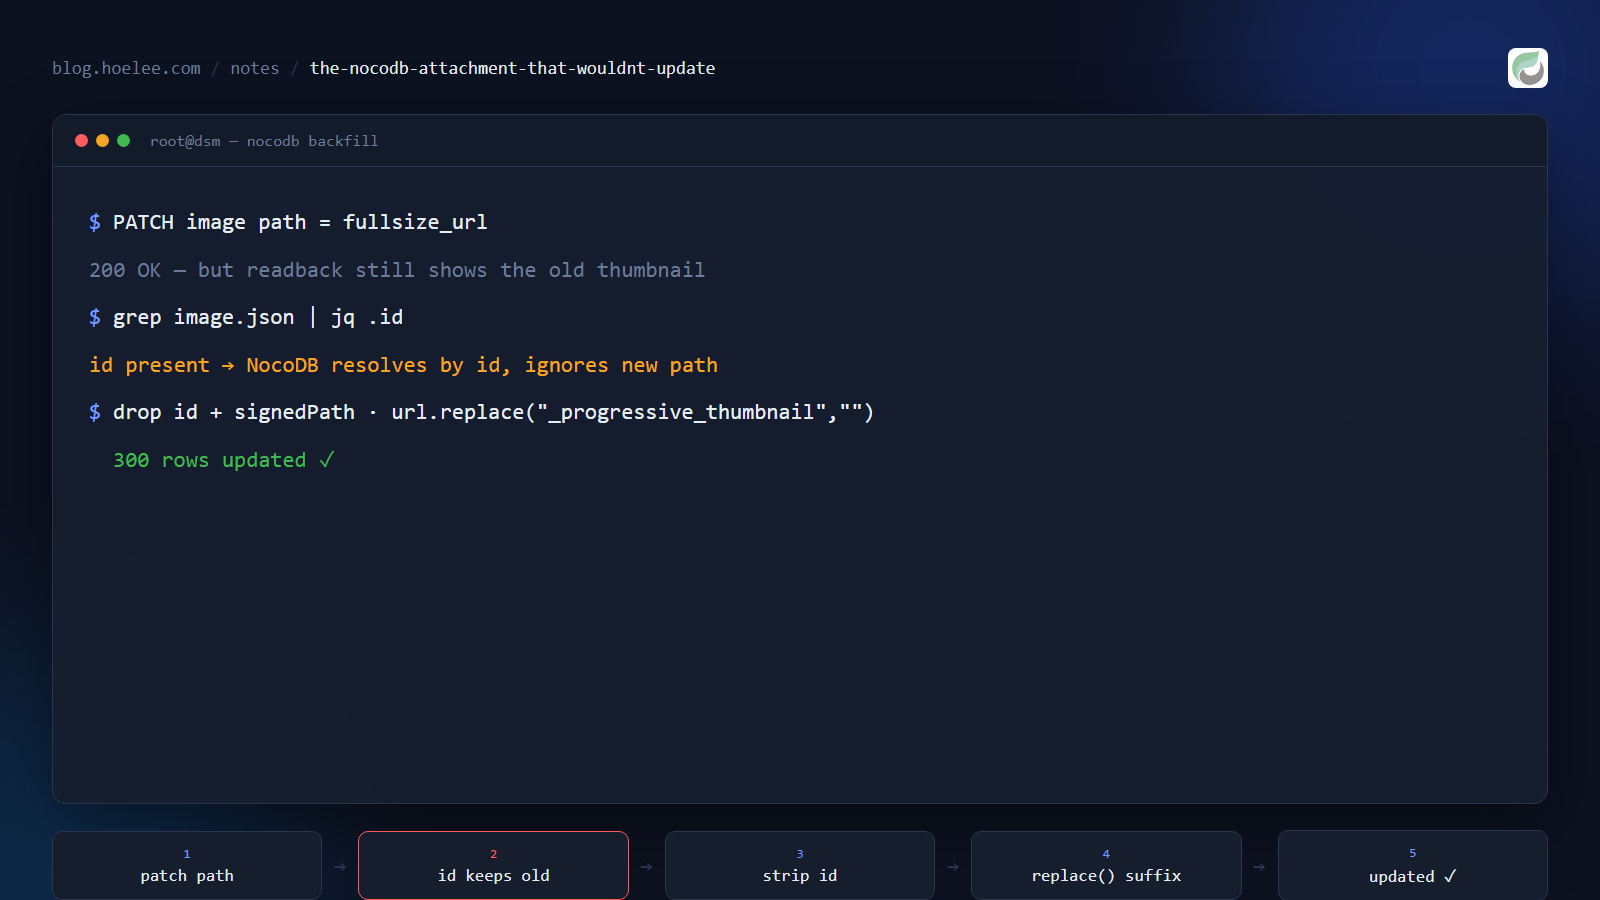
Backfilling 300 rows in NocoDB surfaced two small gotchas that each ate a chunk of time. Both are the kind of thing that only bites you when the data you’re fixing is almost — but not quite — in the shape the code assumes.
Gotcha 1: updating an Attachment’s path doesn’t matter if you keep the id
I wanted to swap every thumbnail URL in an Attachment column for its full-size version. The obvious move is to edit the JSON the column stores:
img = json.loads(row["image"])          # [{"id": "...", "path": "...", "signedPath": "..."}]
img[0]["path"] = new_fullsize_url
img[0]["signedPath"] = new_fullsize_url
It looked like it worked — the PATCH returned success. But reading the rows back,
every path was still the old thumbnail.
The culprit: the attachment carries an NocoDB-generated id, and as long as it’s
present, NocoDB resolves the attachment by that id and happily ignores the new
path. The field I thought I was updating was effectively read-only while the id
was still there.
The fix is to drop the server-assigned fields and let NocoDB re-register the attachment from scratch:
img[0] = {
    "path": new_fullsize_url,
    "mimetype": "image/jpeg",
    "title": img[0].get("title", "image.jpg"),
}
# no "id", no "signedPath" — NocoDB assigns fresh ones
With id gone, NocoDB registers a new attachment from the path and generates a
fresh signed URL. The value finally sticks.
Rule: if a NocoDB Attachment edit isn’t sticking, check for the id field.
Strip it and re-register instead of patching in place.
Gotcha 2: a lookahead regex that silently skipped extension-less URLs
To build the full-size URL I needed to strip the _progressive_thumbnail suffix.
My first pass used a lookahead:
clean = re.sub(r"_progressive_thumbnail(?=\.\w+$)", "", url)That works for:
...70776f54_progressive_thumbnail.jpg → ...70776f54.jpg ✅But Carousell serves two URL shapes. Some thumbnails end with the bare suffix and no extension:
...f94af259_progressive_thumbnail → (lookahead doesn't match) ❌Because the lookahead requires .\w+ at the end, the second shape slipped through
unmatched — 25 of my 300 rows. The regex “worked,” it just silently didn’t do
anything on that slice of the data.
The robust version is a plain replacement, which handles both:
clean = url.replace("_progressive_thumbnail", "")Rule: when normalizing a string that has multiple real-world shapes, prefer
replace() over a regex unless you’ve enumerated every shape. A regex that
silently skips is worse than one that fails loudly.
Nothing here is exotic. But both are the boring kind of bug that only reveals itself in real data — the attachment the API swears it updated, the regex that matches 91% of the rows and says nothing about the other 9%. If backfilling data into NocoDB ever feels like it’s half-working, these two are where I’d look first.